Logistic Regression
Supervised machine learning algorithm used for classification problems.
Uses sigmoid function to convert inputs into probability
For multiple classes, we can use softmax function
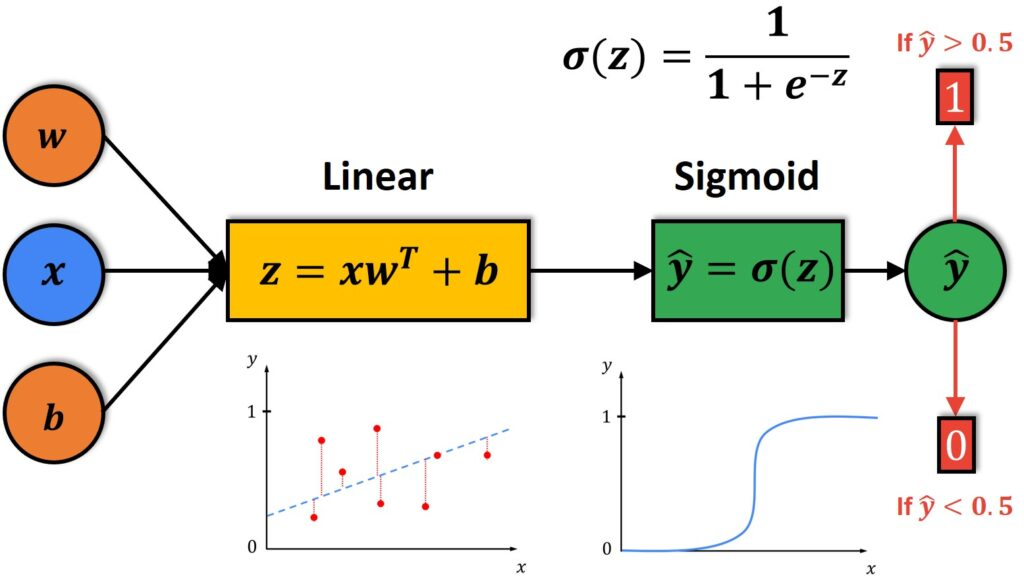
Assumptions
- Independent observations
- Binary dependent variables
- Linearity relationship between independent variables
- No outliers
- Large sample size
Implementation
from sklearn.datasets import load_breast_cancer
from sklearn.linear_model import LogisticRegression
from sklearn.model_selection import train_test_split
from sklearn.metrics import accuracy_score

X, y = load_breast_cancer(return_X_y=True)

X_train, X_test, y_train, y_test = train_test_split(X, y, test_size=0.20, random_state=23)

clf = LogisticRegression(max_iter=10000, random_state=0)
clf.fit(X_train, y_train)

acc = accuracy_score(y_test, clf.predict(X_test)) * 100
print(f"Logistic Regression model accuracy: {acc:.2f}%")
Regularisation Type (L1 vs L2)
Regularisation adds a penalty to the loss function based on the size of model’s weights to ensure that no single feature dominates the prediction. It is used to prevent over fitting. Improves generalisation
Lasso Regression (L1 Regression)
- Least absolute shrinkage and selection operator
- It adds the absolute value of magnitude of the coefficient as a penalty term to the loss function. This penalty can shrink some coefficients to zero which helps in selecting only important features and ignoring the less important ones.
Cost=n1∑i=1n(yi−yi^)2+λ∑i=1m∣wi∣
Ridge Regression
- It adds the squared magnitude of the coefficient as a penalty term to the loss function. It works best for multicollinearity. It shrinks the coefficients of correlated features instead of eliminating them.
Cost=n1∑i=1n(yi−yi^)2+λ∑i=1mwi2
Regularisation Strength
A hyper-parameter that controls how heavily the model can prevent over-fitting. A high value forces smaller weights, reducing over-fitting but risking under-fitting, while lower weight risks over-fitting.
Solver
A solver is an optimization algorithm used to find the best weights that minimise the loss function.
Decision Threshold
Threshold to decide the probability. Can be selected using ROC curves